Illustrate 10,000 Pages a Month With Real Photos — in 500 API Calls
Search once per topic cluster instead of once per image, and 40,000 API calls become 500. The pool-and-assign pattern, the worker that survives rate limits, and an honest section on what photographs cannot fix.
 Marouane Tijani
12 min read

There is a version of the content-illustration problem that no amount of good taste solves: you are not choosing a photo, you are filling 40,000 image slots a month across 800 topic clusters, 9 locales and 14 client sites, and every one of them needs to be licensed, credited, sized and different from the one next to it. At that volume the question stops being “which photo?” and becomes “what is the architecture?”
This article is the API answer: the request pattern that collapses the call count by two orders of magnitude, the worker that survives rate limits, the deduplication that keeps a 10,000-page site from looking like a wall of the same stock photo — and an honest section on what pictures cannot do for you.
The real bottleneck at 10,000 articles
Teams publishing at volume — programmatic SEO estates, marketplace category pages, aggregators, affiliate networks, agencies running content for a portfolio of clients, localisation pipelines turning one article into 20 — all hit the same three walls, in the same order:
- Call count. One search per image slot means 40,000 API calls for 10,000 four-image articles. Every provider prices, throttles and reviews you on that number.
- Repetition. Around page thirty, the same photo starts reappearing. At page three thousand, your site has a visual signature: generated in bulk.
- Coordination. A hundred articles in one cluster should look like a series, not a hundred unrelated Pinterest boards — and the next locale of the same article should reuse the same picture, not search again in another language.
Notice what is not on that list: finding a good photo. A semantic engine returns a page of usable candidates in about 130 milliseconds. Retrieval was solved; distribution was not. Everything below is about distribution.
Why real photos, specifically at this volume
The case for photography over generation gets stronger as volume goes up, for reasons that are mostly operational rather than aesthetic.
| At 40,000 images/month | Generating them | Searching them |
|---|---|---|
| Time per image | Seconds to minutes, plus the rejected attempts | One request (~130 ms) covers a whole cluster |
| Cost driver | Per image, forever | Per request — and one request serves ~25 articles |
| Metadata you get | None. You write the alt text and the dimensions yourself | Dimensions, dominant colour, blur hash, caption draft, credit line |
| Provenance | Machine-marked as synthetic under the EU AI Act since 2 August 20261 | A named photographer, a date, a source URL a reader can open |
| Failure mode | Plausible but wrong details, uniform house style | Nothing matched the brief — you get zero results, which you can handle |
The metadata row is the one that decides pipelines. Every search result already carries
width, height, blur_hash, color_hex,
alt_description and a ready-made attribution.html string — which is
exactly the payload a templating engine needs to emit a layout-shift-free
<img> with a placeholder and a credit. Generated images give you a file and
leave the other six fields for you to invent.
Where generation still wins at scale. Category-level illustration for abstract taxonomies (“cloud migration”, “index funds”), diagrams, and a house style you want repeated across an entire estate for brand reasons. The split most large publishers land on: photographs for anything that exists in the world, generated art for anything that only exists in an argument. We made the full case for that split in how to illustrate every article you publish.
One request, one hundred photos
This is the single change that reshapes the arithmetic. The search endpoint takes
per_page up to 100, and cursor pagination lets you keep walking the
same ranked result set. So the unit of work is not an image, it is a pool.
curl -sG "https://api.pexafy.com/api/v1/search/photos" \
  -H "X-Api-Key: $PEXAFY_API_KEY" \
  --data-urlencode "q=a woman signing paperwork with an insurance agent at a kitchen table in her home" \
  --data-urlencode "per_page=100" \
  --data-urlencode "orientation=landscape" \
  --data-urlencode "score_threshold=0.5" \
  --data-urlencode "fields=photo_id,urls,width,height,blur_hash,alt_description,attribution"

# → { "success": true, "data": [ …up to 100 photos… ],
#     "pagination": { "per_page": 100, "has_more": true, "next_cursor": "eyJyc…" },
#     "meta": { "took_ms": 122.33, "request_id": "7ff1fb9b-…" } }
Three parameters in there are doing quiet work at scale:
fields— a sparse fieldset. Ask for the seven fields your template renders and the response stops shipping the long AI description of every photo. Across 40,000 photos that is the difference between a build that streams and one that swaps.score_threshold— the tail of a 100-result page is, by definition, less relevant than the head. Setting a floor means a thin cluster returns 34 photos instead of 100 mediocre ones, and your pipeline can react to that instead of publishing it.next_cursor— when a cluster genuinely needs 300 photos, paginate the same ranked set rather than firing three different queries that overlap.
And here is the arithmetic, for a site publishing 10,000 pages a month with four images each:
| Strategy | Requests / month | One pass at the free plan's rate limit20 req/min | Fits the free monthly quota? |
|---|---|---|---|
| One search per image slot | 40,000 | 33 hours | No — a paid plan |
| One search per article | 10,000 | 8 hours | No — a paid plan |
| One search per cluster of ~20 articlesthe pattern in this article | 500 | 25 minutes | Yes |
Same 40,000 published images in all three rows. The only thing that changed is where the loop sits.
Pool and assign: the pattern that scales
The whole architecture is two phases that run at different frequencies, with a table between them:
                     ┌─────────── runs weekly, ~500 requests ───────────┐
  topic clusters ──▶ POOL   search once per cluster, per_page=100
                     │       └─▶ store 100 photo rows per cluster
                     └──────────────────┬───────────────────────────────┘
                                        ▼
                              image_pool table
                        (cluster, photo_id, urls, blur_hash,
                         alt, credit, used_by_page, used_at)
                                        │
                     ┌──────────────────┴──── runs per publish, 0 requests ───┐
  article ─────────▶ ASSIGN  pick the best unused row for this
                     │        cluster, mark it used, render
                     └────────────────────────────────────────────────────────┘
What this buys you, in order of how much it matters at volume:
- Publishing never blocks on an API. Assignment is a database read. Your CMS save hook, your static build and your 3 a.m. bulk import all run at local speed, offline, with no rate limit anywhere in the path.
- Deduplication is free and exact.
used_by_page IS NULLis the whole feature. Two pages cannot draw the same photo, because assignment is a transaction, not a ranking heuristic. - Re-runs are cheap and idempotent. Refresh a cluster's pool when it runs low
or when you want newer photography (
after_date, orsort_by=newest) — one request, and nothing already published moves. - Locales come for free. The 20 translations of an article are one page in
your model with 20 renderings; they share the assigned
photo_idand you never search twice. When you do want a locally-shot look, run the pool query for that cluster in the target language — the engine takes a sentence in over 100 of them.
The worker, in code
Roughly sixty lines. The pool filler is the only part that talks to the network, so it is the
only part that needs to be careful — concurrency capped, 429 respected, results
written in one transaction.
import asyncio, os, time, httpx

SEARCH = "https://api.pexafy.com/api/v1/search/photos"
KEY    = os.environ["PEXAFY_API_KEY"]
FIELDS = "photo_id,urls,width,height,blur_hash,alt_description,attribution"

# Free = 20 req/min. Stay one under. The pacer is GLOBAL: a per-task sleep
# inside the concurrency gate would let N workers fire N× the rate.
PER_MIN = 19
gate    = asyncio.Semaphore(4)         # in-flight connections
_lock   = asyncio.Lock()
_slot   = 0.0                          # next free moment on the shared timeline

async def pace():
    """Hand out one request slot every 60/PER_MIN seconds, fleet-wide."""
    global _slot
    async with _lock:
        now  = time.monotonic()
        _slot = max(now, _slot) + 60 / PER_MIN
        wait  = _slot - now
    if wait > 0:
        await asyncio.sleep(wait)

class QuotaExhausted(Exception): ...   # monthly: retrying cannot help

async def fill_pool(client, cluster) -> list[dict]:
    """One request → up to 100 credited photos for one topic cluster."""
    for attempt in range(4):
        await pace()
        async with gate:
            r = await client.get(
                SEARCH,
                headers={"X-Api-Key": KEY},
                params={
                    "q": cluster["camera_brief"],   # a scene, not the keyword
                    "per_page": 100,
                    "orientation": "landscape",
                    "score_threshold": 0.5,
                    "fields": FIELDS,
                },
                timeout=15,
            )
        if r.status_code == 429:
            retry_after = r.headers.get("Retry-After")
            if retry_after is None:            # no Retry-After ⇒ monthly quota,
                raise QuotaExhausted(cluster["id"])   # stop the whole run
            await asyncio.sleep(int(retry_after))   # per-minute: it clears
            continue
        r.raise_for_status()
        return r.json()["data"]
    return []                                  # log it; the pool keeps its old rows

async def refill(clusters):
    async with httpx.AsyncClient(http2=True) as client:
        pools = await asyncio.gather(*(fill_pool(client, c) for c in clusters))
    for cluster, photos in zip(clusters, pools):
        db.upsert_pool(cluster["id"], photos)     # ON CONFLICT DO NOTHING on photo_id
Two details in there are the difference between a worker that runs unattended and one that
wakes you up. The pacer is global, not per-task: putting the sleep inside the
concurrency gate is the classic mistake — four workers each pausing 3 seconds after their
own request produce four requests every 3 seconds, roughly 75 a minute, and the free plan
starts returning 429 immediately. And the two 429s are not the same
animal: the per-minute one carries Retry-After and clears itself, the monthly-quota
one does not carry it and never will — retrying that is a loop against a wall.
Assignment, the part that runs on every publish, never touches the network:
# Uniqueness is enforced by the schema, not by the query being careful.
# A photo can sit in several cluster pools; it may be PUBLISHED only once.
# CREATE UNIQUE INDEX one_use_per_photo ON image_pool (photo_id)
#        WHERE used_by_page IS NOT NULL;

def assign_hero(page_id: str, cluster_id: str) -> dict | None:
    for _ in range(5):                # a lost race just takes the next photo
        try:
            return db.query_one("""
                UPDATE image_pool p SET used_by_page = %s, used_at = NOW()
                WHERE p.id = (
                    SELECT c.id FROM image_pool c
                    WHERE c.cluster_id = %s AND c.used_by_page IS NULL
                      AND NOT EXISTS (              -- used by ANY other cluster?
                          SELECT 1 FROM image_pool u
                          WHERE u.photo_id = c.photo_id
                            AND u.used_by_page IS NOT NULL
                      )
                    ORDER BY c.rank ASC
                    LIMIT 1 FOR UPDATE SKIP LOCKED  -- safe with parallel workers
                )
                RETURNING photo_id, urls, width, height, blur_hash, alt, credit
            """, [page_id, cluster_id])
        except UniqueViolation:      # two clusters claimed it in the same ms
            continue
    return None                     # pool dry → widen the brief, refill

# Rendering: every attribute comes from the row — no layout shift, no guessing.
# <img src="{urls[regular]}" width="{width}" height="{height}"
#      alt="{alt}" loading="lazy" style="background:{blur_placeholder}">
# <figcaption>{credit}</figcaption>
Two failure modes, two mechanisms, and both are needed. FOR UPDATE SKIP LOCKED
handles concurrency within a cluster: generate pages in parallel — and at this volume
you will — and two workers reach for the same top-ranked photo in the same millisecond.
The partial unique index handles the one everybody forgets: the same photo legitimately appears
in the pools of several clusters, because neighbouring clusters (“home insurance for
renters”, “…for landlords”) return overlapping results. A per-cluster
used_by_page IS NULL check is blind to that — each cluster believes the photo is
free. The NOT EXISTS keeps the query honest, and the index makes it impossible to
get wrong under concurrency: the loser of the race gets a violation, retries, and takes the next
photo. Without it, “no two pages share a hero” is a claim, not a guarantee.
When a pool runs dry mid-build, the fallback that behaves best is to widen rather than repeat: drop the last clause of the camera brief, re-run the pool query once, and only then reuse the oldest-assigned photo — with a hard rule that it never lands on a page in the same cluster.
One cluster, one pool: a real query
Take a comparison estate: home insurance, twenty pages — “home insurance for renters”, “…for landlords”, “what a policy actually covers”, twelve city pages, three claim guides. One camera brief for the cluster, one request, and this is the head of the pool, returned in 122 ms:
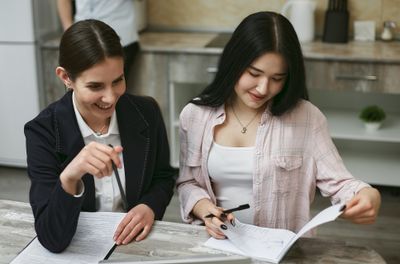
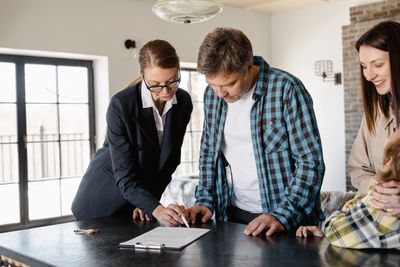
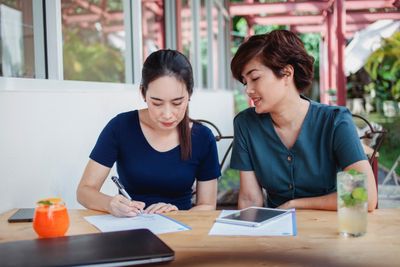
per_page=100 and keeps the rest.
Run this exact search →
The briefs matter more than the code. Two rules survive contact with a real estate of clusters:
write the brief for the cluster, not for the page (page titles are near-identical
across programmatic sets, so per-page briefs return near-identical photos), and describe a scene
a camera could have taken rather than the topic — home insurance returns document
close-ups and nothing else. We published the copy-pasteable prompt that produces these briefs in
the article on illustrating every post.
Keeping a 200-page series visually coherent
The opposite failure of repetition is incoherence: twenty pages in one cluster, each with a
technically-correct photo, in twenty different visual registers. The fix is one endpoint —
GET /photos/{id}/similar — run once on the photo you approved for the pillar page:
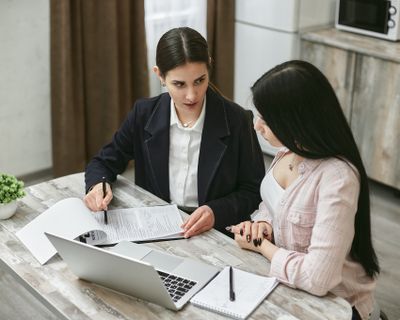
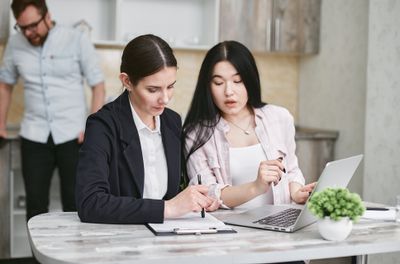
Two more levers worth wiring into the pool query when brand consistency is a requirement:
color_hex with a color_tolerance keeps a whole estate inside a
palette, and photographer pins a cluster to one photographer's body of work. Both
are ordinary query parameters — no plan gating on search filters.
Rate limits, quotas and what it actually costs
Pick the plan on burst, not on volume. Once you pool, the monthly quota stops being the constraint for almost everybody; what decides your plan is how fast a full refresh has to finish.
| Plan | Requests / month= clusters refreshable | Rate limit | API keys | Refresh 1,000 clusterswall-clock, one pass |
|---|---|---|---|---|
| Free — $0 | 5,000 | 20 / min | 1 | 50 min |
| Starter — $5 | 25,000 | 30 / min | 3 | 34 min |
| Pro — $19 | 100,000 | 60 / min | 5 | 17 min |
| Team — $99agencies: a key per client | 500,000 | 200 / min | 25 | 5 min |
| Business — $249 | 1,000,000 | 300 / min | unlimited | 4 min |
| Enterprise — $599 | 2,000,000 | 500 / min | unlimited | 2 min |
Read the first column as clusters: one pooling request fills one cluster, so the monthly quota is the number of clusters you can refresh, and the last column is how long a full pass over a 1,000-cluster estate takes at that plan's rate limit. Both are live values from the pricing catalogue — the pricing page states the same rate limits per hour rather than per minute.
So a 10,000-page-a-month estate on the pooled pattern spends ~500 requests and pays nothing. What pushes teams up the table is rarely volume — it is one of three things: a full re-illustration of an existing estate in one night, per-client key isolation (an agency wants one key per client so usage is attributable without shared-secret gymnastics), or a build window measured in minutes rather than hours.
Two operational details that save a night of debugging. Every response carries
X-RateLimit-Limit and X-RateLimit-Remaining, so a worker can pace
itself instead of guessing. And a 429 that is a true per-minute rate limit carries
Retry-After, while a monthly-quota block deliberately does not — retrying
will not clear that one, and a worker that distinguishes the two stops hammering an endpoint
that has nothing left to give.
When the agent does the publishing
If your content is produced by an agent — and at these volumes it increasingly is — the pooling
layer does not disappear, it moves. Give the agent the search tools and it fills the pool while
it still holds the cluster brief in context, using the
Model Context Protocol server at mcp.pexafy.com/mcp: three tools,
search_photos (a sentence), search_photos_by_image (a reference image,
optionally plus a sentence) and get_similar_photos (the series-coherence one from above).
# Claude Code / CI runner
claude mcp add --transport http pexafy https://mcp.pexafy.com/mcp \
  --header "Authorization: Bearer $PEXAFY_API_KEY"

# or commit .mcp.json so every worker in the fleet inherits it
{
  "mcpServers": {
    "pexafy": {
      "type": "http",
      "url": "https://mcp.pexafy.com/mcp",
      "headers": { "Authorization": "Bearer YOUR_API_KEY" }
    }
  }
}
The instruction that works at scale is a batch instruction, not a per-article one — and it maps one-to-one onto the two phases above:
You  Here are 12 topic clusters from the content calendar. For each,
     write one camera brief, pull 100 landscape photos, and write
     the pool to Postgres. Flag any cluster that returns under 40
     results above 0.5 — those briefs need rewriting.

Agent  → search_photos(q="a woman signing paperwork with an insurance
           agent at a kitchen table in her home", orientation="landscape")
      ← 100 photos · 122 ms · 87 above threshold
      … 11 more clusters …

      ✓ 11 pools written (1,043 photos, all credited)
      ⚠ "index fund rebalancing" → 12 results. The brief is abstract;
        suggest: "a person at a kitchen table checking figures on a
        laptop with a notebook and coffee beside them"
That last line is the reason to put the agent in this loop rather than a script: the failure mode of programmatic illustration is a bad brief, and a bad brief is exactly the thing a language model can notice and rewrite. The scripts stay in charge of assignment, where determinism matters and creativity does not.
What photographs cannot fix
An honest section, because the failure it describes is expensive. Real, credited photography improves a page. It does not turn thin content into good content, and no image pipeline changes how search engines treat mass-produced pages that exist to rank rather than to help. Google's spam policies name this directly: scaled content abuse covers generating many pages with little value whether or not automation is involved, and the illustrations on those pages are irrelevant to that judgement.2
So the useful framing is narrow and true: photography is a quality signal you control on pages that already deserve to exist. Where it demonstrably pays off:
- Provenance a reader can verify. A credit line with a photographer's name and a source URL is a claim that can be checked — the opposite of an unattributed image on a page with an unattributed author.
- Accessibility and Core Web Vitals.
width/heightfrom the response kill layout shift,blur_hashgives a real placeholder, andalt_descriptionis a draft of alt text your template can improve rather than invent. Multiply by 40,000 slots and this is the whole image-quality story of the site. - Not looking mass-produced. Deduplication and series coherence are what stop an estate from having a visual signature. That is a real perception cost with real consequences, and it is entirely under your control.
And the licence still governs the picture. Attribution is not required by the Pexafy API terms —
every result ships attribution.html and attribution.plain ready to
render — but the licence attached by the original library applies to your use of that photo, and
at 40,000 images a month, rendering the credit automatically is cheaper than auditing later.
Where to start on Monday
- Group your backlog into clusters of 15–30 pages that could plausibly share a photo shoot. This is the only genuinely manual step, and it is a spreadsheet, not a project.
- Write one camera brief per cluster — a scene, 12 to 25 words. Generate them with a model, then read them; briefs that name a topic instead of a scene are visible at a glance.
- Fill one pool with a single
per_page=100request and eyeball the head of it. If the top ten are not usable, the brief is wrong — not the engine. - Add the
used_by_pagecolumn before you publish anything. It is five minutes now and a migration across 3,000 live pages later. - Run the whole thing on the free plan until a build window forces you up. At 500 requests a month, it will take a while.
References & footnotes
1 EU AI Act, Article 50 — transparency obligations applicable from 2 August 2026: providers of systems generating synthetic image, audio, video or text must mark outputs in a machine-readable format and make them detectable as artificially generated. It binds AI providers and deployers; it is not a rule about which images a website may publish.
2 Google Search spam policies — scaled content abuse: generating many pages primarily to manipulate rankings and offering little value to users, whether created through automation, human effort or a combination. Illustration quality is not a factor in that assessment, which is precisely why this article separates the two.
Sources checked on 17 August 2026: Google Search spam policies · AI Act Article 50 · Pexafy API & MCP docs. Plan limits are the live values from the Pexafy pricing table; the search timings (122 ms, 48 ms) and every photo shown are real API responses captured the same day.
Frequently asked questions
How do I get images for thousands of programmatic SEO pages?
GET /api/v1/search/photos request with per_page=100 returns up to 100 credited photos for one cluster; you store them in a pool table and assign one per page at publish time. A 10,000-page-per-month estate with four images per page needs roughly 500 requests instead of 40,000, which fits inside the free plan (5,000 requests/month).What is the best stock photo API for high-volume content production?
How do I stop the same stock photo appearing on several pages?
photo_id of every image you publish and claim photos from the pool transactionally — in SQL, an UPDATE … WHERE used_by_page IS NULL … FOR UPDATE SKIP LOCKED. Deduplication then becomes exact rather than probabilistic, and parallel build workers cannot race for the same top-ranked photo. It is one column, and retrofitting it across thousands of live pages is far more expensive than adding it on day one.How many photos can one API request return?
per_page=100, and cursor pagination lets you keep walking the same ranked result set for deeper pools. Combine it with score_threshold so a thin cluster returns 40 strong matches rather than 100 loose ones, and with fields to return only the attributes your template renders, which keeps responses small at volume.Do real photos help pages produced at scale rank better?
Can an AI agent fill an image pool automatically?
mcp.pexafy.com/mcp, which exposes search_photos, search_photos_by_image and photo_similar. Give the agent a list of clusters and it writes one camera brief each, pulls the pools and flags the briefs that returned too few strong matches — which is the actual failure mode of programmatic illustration. Assignment stays in your scripts, where determinism matters more than creativity.

